
Book an intro callBook an intro call with Karl

Pressure-test your
app, website, or AI
against real 
people
& expert judgment
Save months of wasted effort with independent evaluation, messaging, & UX research

An independent research practice. Fixed-price reviews and studies, each ending in a ranked list of what to change first

A UX research & AI evaluation consultancy. Fixed-price reviews and studies, each ending in a ranked list of what to change first

Reviews and studies run by Karl Neumann, each with a fixed price and a ranked list of what to change first

Independent AI evaluation, product messaging, & UX research

AI evaluation, product messaging, & UX research for apps, websites, & AI

Desire Path is Karl Neumann’s consultancy for AI evaluation, product messaging, & UX research

A desire path is the trail people wear across the grass when the sidewalk doesn’t go where they want to go. See them in a product

Founders, partners, and teams building apps, websites, and AI

Clients & partners

Getting started

  1. Book an intro call

    30 minutes, free. Describe what you’re building and what you want to improve

  2. Get a scope & approach

    Receive a written plan with timelines, options, & prices within 48 hours of the intro call

  3. Kickoff

    We answer questions, discuss first impressions, share quick wins, and set expectations

Two ways to work togetherWays to work togetherWork with Desire PathServicesHow we can work together

For teams building apps, websites, or AI. You get a findings brief and a session to decide what to change first

  • Expert review1-5 daysEvaluation of your website, messaging, product, & analytics, from first impressions to retention
  • Research with your audience1-4 weeksdepending on recruitingUsability studies, interviews, surveys, A/B tests, or message tests, with timing set by recruiting
  • AI evaluation2-6 weeksExperts from your field grade your AI’s replies or compare them with a person’s, starting with a rubric test
  • Ongoing supportWeekly or retainerGet advisory, fractional, or embedded expertise without a full-time hire
See the workAI evaluation

For teams building apps, websites, or AI. You get a findings brief and a session to decide what to change first

  • Expert review1-5 daysEvaluation of your website, messaging, product, & analytics, from first impressions to retention
  • Research with your audience1-4 weeksdepending on recruitingUsability studies, interviews, surveys, A/B tests, or message tests, with timing set by recruiting
  • Rubric testAbout 2 weeksTwo experts from your field grade 25 of your AI’s replies, $3,000 fixed,, and it sets up another studyTwo experts from your field test your AI’s rubric on 25 replies, or help you draft one, before a full study
  • Grading study4-6 weeksFive experts score your AI’s replies on a rubric. Find where they agree and disagree on tough calls
  • Comparison study4-6 weeksExperts blindly judge human & AI replies to the same prompts, and you see how the AI compares
  • Ongoing supportWeekly or retainerGet advisory, fractional, or embedded expertise without a full-time hire

See the workSee AI evaluation

Product & UX evaluation

For founders and teams building apps or websites. Every project ends with a ranked list of what to change firstEvery project ends with a findings brief and a working session to decide what to change firstYou get a findings brief and a session to decide what to change first

  • Expert review1-5 daysEvaluation of your website, messaging, product, & analytics, from first impressions to retention
  • UX copywriting[timing]In every review1-2 weeksReview of copy across your app, website, & outreach, rewrites where needed, and a style guide
  • Research with your audience1-4 weeksdepending on recruitingUsability studies, interviews, surveys, A/B tests, or message tests, with timing set by recruiting
  • Ongoing supportWeekly or retainerGet advisory, fractional, or embedded expertise without a full-time hire
See the work

AI evaluation

For heads of AI, medical directors, and trust & safety leads at companies shipping AI where a wrong answer costs a lotFor medical directors and heads of AI in healthcare, and AI teams in law, HR, & housing where a wrong reply costs a lotFor medical directors and heads of AI in high-risk domains like healthcare, law, HR, & housingFor medical directors and heads of AI in healthcare, law, HR, & housingFor medical directors, heads of AI, and clinical safety leads at companies whose AI answers patients or clinicians

  • Rubric testAbout 2 weeksTwo experts from your field grade 25 of your AI’s replies, $3,000 fixed,, and it sets up another studyTwo experts from your field test your AI’s rubric on 25 replies, or help you draft one, before a full study
  • Grading study4-6 weeksFive experts score your AI’s replies on a rubric. Find where they agree and disagree on tough calls
  • Comparison study4-6 weeksExperts blindly judge human & AI replies to the same prompts, and you see how the AI compares
  • AI feature test1-4 weeksPeople try your AI feature with minimal guidance, to see what they understand, trust, and act on

See AI evaluation

Selected work

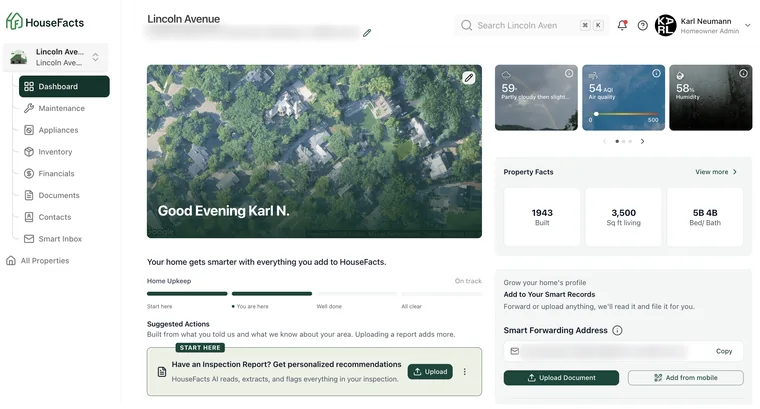
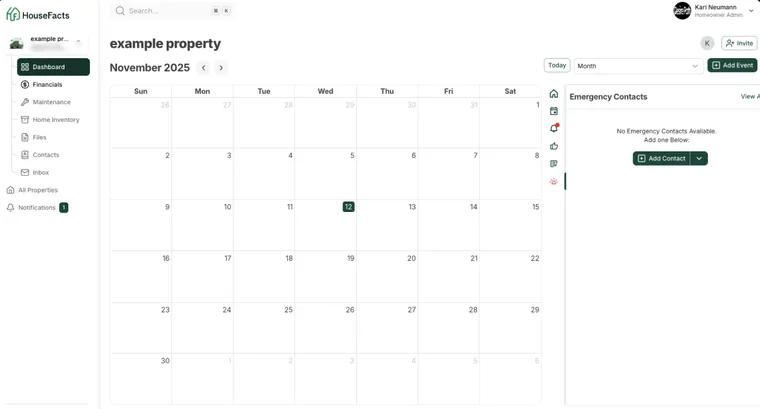
HouseFacts dashboard now: an aerial photo of the home, local weather and air quality, property facts, and a home upkeep tracker HouseFacts dashboard in October 2025: a month calendar and an empty emergency contacts panel

Tap a number to see what changed and why

Homeowner dashboard · UI designs by the HouseFacts team

Tap a number on the After side to see what changed and why.

The desire paths we found

Supported the iOS launch and the first B2B dealsEmbedded UX, research, & product strategy through app launch and a pivot to B2BEmbedded UX, research, & content design

UI designs by the HouseFacts team

HouseFacts

AI-powered property management platform

Work
Embedded UX research & product partner, with UI designs by the HouseFacts team
Results
  • Conducted eight rounds of usability testing on their web platform, on desktop and mobile, plus a 50-person messaging study
  • Hired their lead product designer and consulted on the design of signup, onboarding, the product tour, and the main dashboard
  • Supported their iOS app launch with App Store, in-app, and onboarding copy. Also reviewed and rewrote every notification across web, push, and email

"Karl's research helps us figure out what to prioritize and who to prioritize. At an early-stage startup there are endless priorities and limited resources, and his research is the foundation for deciding what we do next."

Erin Zamiara, Go-to-market, HouseFacts
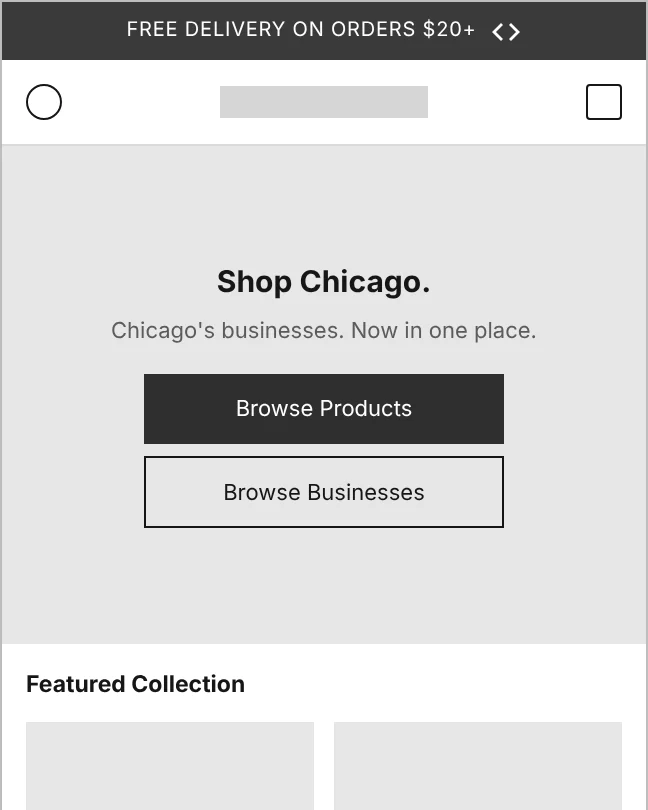
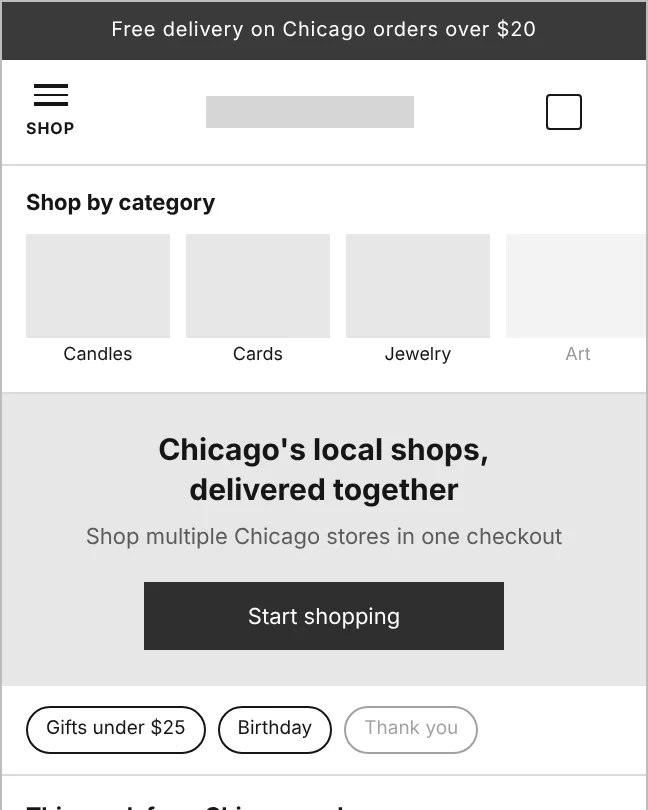
Sherwood Square home page wireframe, proposed: category tiles, one Start shopping button, and gift shortcuts on the first screen Sherwood Square home page wireframe before: a banner with two browse buttons, and no products until the shopper scrolls
Home page redesign · My UI designs in Figma

The desire paths we found

A home page that shows products on the first screenEvaluated the whole store and redesigned every core pageOnline store evaluation & redesignOnline store analytics, evaluation, & redesign

My UI designs in Figma

Sherwood Square

E-commerce marketplace for Chicago stores

Work
Designer: analytics, evaluation, competitive analysis, and my redesign in Figma
Results
  • Analyzed the store’s traffic, advertising, and checkout data, and evaluated the entire UX
  • Redesigned the home page, mobile menu, and category structure in Figma
  • The store is shipping the redesign in stages

"Karl reviewed the whole site as a first-time shopper would and gave me a prioritized list I could build myself in Shopify. I made quite a few updates based on his recommendations ahead of the holidays."

Michael Ulrich, Founder, Sherwood Square
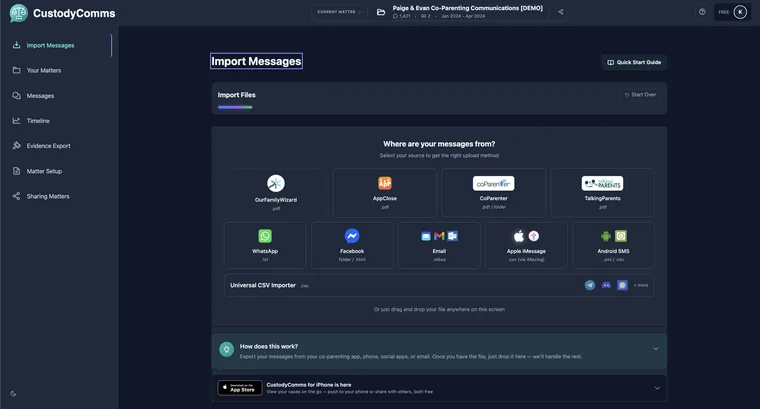
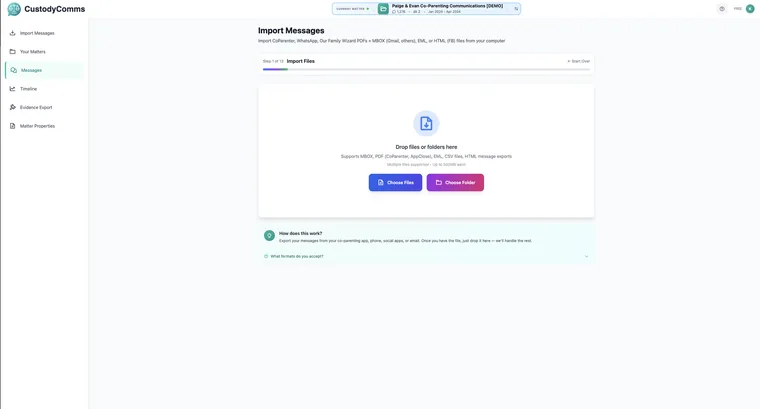
CustodyComms desktop app landing page after: a grid of sources to choose from, including co-parenting apps, WhatsApp, email, and phone messages CustodyComms desktop app landing page before: one empty drop zone with two buttons
Desktop app landing page · UI designs by the CustodyComms team

The desire paths we found

Launched on desktop and iOS, with paying subscribersEvaluated the app, site, and brand before and after launchProduct evaluation & brand direction

UI designs by the CustodyComms team

CustodyComms

Family law communications platform

Work
Evaluator & brand advisor before and after launch, with designs by CustodyComms
Results
  • Advised on their marketing website, landing page, and brand direction, including showing the product before download
  • Consulted before their desktop and iOS launch, the release that brought in their first paying subscribers
  • Recommended the export user guide and a four-color brand, both adopted

"CustodyComms is a better application because of Karl, and we thank him for that."

Tom Malick, CEO, CustodyComms
Book an intro call

30 minutes, free

Shipping AI? A panel of 5 experts grades its answers and shows where they split. Learn about AI evaluation

Selected work

How projects work

  1. Evaluate (1-5 days)Evaluate (1-5 days)Evaluate (1-5 days)

    I review your product, designs, and analytics for friction, gaps, and untested assumptionsI review your product, designs, and analytics, and rank what to fix firstI review your product, designs, and analytics, and rank what to fix first

  2. Test (1-4 weeks)Iterate (1-2 weeks)Iterate (1-2 weeks)

    I run interviews, usability studies, experiments, or usage analysis, whichever fits your stageYour team makes the top fixes, and I review each buildYour team makes the top fixes, and I review each build

  3. Integrate (1-2 weeks)Test (1-4 weeks)Test (1-4 weeks)

    I lead readouts, workshops, and strategy sessions, each tied to a decision we need to makeI test the changes with the people you're building for, measure the results, and walk your team through the findingsI test the changes with the people you're building for and measure the results

  4. IteratePrioritizePrioritize (1-2 weeks)

    We pick the next priority, and I measure what the last change didWe choose what’s next based on the team’s roadmap and what the tests showedI lead a readout or workshop on what we found, and we pick the next priority

AI evaluation

Automated gradersAI evals miss the cases where experts disagree. A panel study finds them.Your AI has to decide when to answer and when to hand off to a person. A panel of outside experts shows where to draw that line.Your AI makes judgment calls your experts disagree on. A panel study shows your team which calls to decide.See where your AI’s answers fall short of your experts. A panel study grades its replies or compares them with a person’s.Is your AI as good as your experts? A panel study grades its replies, compares them with a person’s, and shows where experts split.Grading studies score your AI’s replies
Comparison studies judge AI responses against human replies

In one academic study, experts agreed with each
other ~75% of the time and with AI judges only 65% of the time
In one academic study, experts agreed with each other 73% of the time, and with LLM judges only ~66% of the time (Szymanski et al., 2024).

Theoretical Grading exampleInvented Grading exampleMade-up Grading exampleHypothetical Grading example: a chatbot answering patient messages after hours

Patient

For the past two weeks, my chest keeps feeling tight while going up the stairs, but it goes away after a few minutes. I'm only 52. Should I be worried?

AI reply

A doctor should see you within 24 hours. I've booked a visit for tomorrow morning. If the tightness comes on at rest, call 911.

4 clinicians split 2-2 on this reply. You're the 5th.

Is a visit tomorrow the right level of care?

Split 2-2

You

Right level of care?

  • Family yes
  • Urgent care no
  • Telehealth yes
  • ER no
  • Cardiology no

Split 3-2

  • Family medicine “A visit tomorrow, with clear 911 triggers, is reasonable.”
  • Cardiology “He needs the ER now. Tomorrow is too late.”

Start with a rubric test

A panel study can show where experts disagree or how your AI compares to humans

Grading
Experts score your AI's replies against the standards your field uses
Comparison
Experts judge AI and human replies side by side, without knowing which is which

Where possible, panels review real interactions sampled after launch, so they see what people received.

Panel readoutSample page, invented example

The panel agreed on the wording and split on urgency

5 clinicians graded 30 AI replies to patients. This sample page shows only one: chest tightness on stairs.

  • Right level of care2 of 5 yes
  • Clear signs for when to call 9115 of 5 yes
  • Plain enough for a patient to act on4 of 5 yes

Marks in order: family medicine, urgent care, telehealth, emergency medicine, cardiology

They split over a contested standard
  • Visit within 24 hours2 of 5. A visit tomorrow, with clear 911 triggers, is enough.
  • Emergency room now3 of 5. New chest pain on exertion is unstable until ruled out.
Decision for your team

Which standard should the assistant meet for chest symptoms on exertion?

Decision owner: medical director

For the medical directors, heads of AI, and trust & safety leads working in high-risk use cases like healthcare, law, HR, & housing.

Book an intro call

Panel studies find what to fix. They don't certify an AI as safe.

See AI evaluation

Desire paths reveal what people wantshow what people actually doare the routes people chooseshow where people want to goshow what people actually do

The desire path

The sidewalk

In urban planning, desire paths are the trails people wear into the grass when the sidewalk doesn’t go where they want to go. In a product, they show up in places like these.

I find the paths people want to take so you can build those routes for themI find the gap between how your product was built and how people use it, so you can close itI find the routes people take through your product, so you can build around themI find where people leave the route your product lays out, so the next version follows theirsI find the gaps between what was built and how people useI find the paths people are trying to take in your product, so we can build those routes for themI find where people are trying to go in your product, so we can build the routes they’ll actually useI find the shortcuts people are trying to take in your product, so we can pave themI find the shortcuts people are trying to take in your product, so we can build those routes for themI find the shortcuts people are trying to take in your products, so we can build those desire paths for them

In products, desire paths show up as

  • The steps people skip
  • The words people look for
  • The pages people open first
The flow that was built: five screensThe desire path: one step

When to reach out

Which sounds familiar? Tap one to see where a project would start.

  • Shipping AI soonShipping high-⁠stakes AIBuyers and investors ask how your AI was testedAre the AI's answers right?But no outside expert has checked its answers yetBut no outside expert has checked its answersYour own evals are the only answer so farExperts in your field grade them before launchHow a panel study works

    Rubric test Two experts from your field grade 25 of its replies, so you know which criteria a graderyour AI evals can be built on. About two weeks, $3,000 fixed. Start with a rubric test

  • Traffic, but no salesLots of visitors, few buyersWhere do visitors drop off?And you can't tell which part loses peopleMost leave partway, and you can’t tell whereFind the step between visit and sale that loses them

    Site and data review An evaluation of the site and its traffic data shows where shoppers drop off and what to fix first. This is where the Sherwood Square project started.

  • Five taglines, five opinionsFive taglines, five opinionsWhich tagline works best?Your team keeps arguing about what people wantThe team can't agree on a directionTest them with the people you sell to

    Message test The people you sell to compare the options, and you see which one wins and why.

  • Ready to ship, but never testedBuilt, but never testedWill people get it?Nobody outside your team has tried it yetNobody outside the team has tried itPeople outside your team try it before you ship

    Usability test People outside your team try the product, and you see where they get stuck before launch.

  • Launched, but usage is flatLaunched, but usage is flatWhy is usage flat?And the dashboards don't say whyThe dashboards don't say whyFind out what the dashboards can't show

    Interviews With people who signed up and stopped, so you hear their reasons in their own words.

  • People like it, but won't pay for itPeople like it, but won't payWhy won't people pay?Free accounts stay free, and pilots never become contractsFree accounts stay free, and pilots never turn into contractsFind out what would turn free accounts and pilots into contracts

    Interviews and a message test Talk with free accounts and pilot buyers, then test your offer, so you see what would make them pay.

Before launch

  • Ready to ship, but never testedBuilt, but never testedWill people get it?Nobody outside your team has tried it yetNobody outside the team has tried itPeople outside your team try it before you ship

    Usability test People outside your team try the product, and you see where they get stuck before launch.

  • Five taglines, five opinionsFive taglines, five opinionsWhich tagline works best?Your team keeps arguing about what people wantThe team can't agree on a directionTest them with the people you sell to

    Message test The people you sell to compare the options, and you see which one wins and why.

  • Shipping AI soonShipping high-⁠stakes AIBuyers and investors ask how your AI was testedAre the AI's answers right?But no outside expert has checked its answers yetBut no outside expert has checked its answersYour own evals are the only answer so farExperts in your field grade them before launchHow a panel study works

    Rubric test Two experts from your field grade 25 of its replies, so you know which criteria a graderyour AI evals can be built on. About two weeks, $3,000 fixed. Start with a rubric test

After launch

  • Traffic, but no salesLots of visitors, few buyersWhere do visitors drop off?And you can't tell which part loses peopleMost leave partway, and you can’t tell whereFind the step between visit and sale that loses them

    Site and data review An evaluation of the site and its traffic data shows where shoppers drop off and what to fix first. This is where the Sherwood Square project started.

  • Launched, but usage is flatLaunched, but usage is flatWhy is usage flat?And the dashboards don't say whyThe dashboards don't say whyFind out what the dashboards can't show

    Interviews With people who signed up and stopped, so you hear their reasons in their own words.

  • People like it, but won't pay for itPeople like it, but won't payWhy won't people pay?Free accounts stay free, and pilots never become contractsFree accounts stay free, and pilots never turn into contractsFind out what would turn free accounts and pilots into contracts

    Interviews and a message test Talk with free accounts and pilot buyers, then test your offer, so you see what would make them pay.

Book an intro call

30 minutes, free

Who you'll be working with

Karl Neumann, smiling, in a dark blazer and white shirt on a city street

I started Desire Path in Chicago in 2025 and run every user research study, AI evaluation, and workshop myself

Karl Neumann, founder & principal

  • Employee #8 at Memora Health, Seed to Series B
  • Led UX research at Kooth Digital Health
  • Evaluating AI since 2019
More about Karl

Who you'll work withAbout Karl

Karl Neumann, smiling, in a dark blazer and white shirt on a city street
Karl Neumann, founder & principal

I started Desire Path in Chicago in 2025 and run every user research study, AI evaluation, and workshop myself

Before Desire Path

  • Fortune 500 consultingFor healthcare clients with ZS Associates
  • From 0 to >100k usersLed UX research at Kooth Digital Health and sat on its Global AI Ethics Committee
  • App store ratings from 3.2 to 4.6 starsResearch-led design changes at Kooth Digital Health, on iOS and Android
  • Scaled Seed to Series BEmployee #8 at Memora Health, a Y Combinator conversational AI startup. Evaluating AI since 2019
  • Publications & talksBMJ Innovations paper on testing a postpartum chatbot before it reached patients. Plus 2026 Quant UX Con talk on what expert panels catch that AI evals miss

Talks & writing

FAQs

  • What does a project cost?What does a project cost?How does pricing work?

    After a free call, I send a written scope & approach with timelines, options, & prices within 48 hours. Reviews and studies are a fixed price, and ongoing support is billed hourly or as a flat retainer.

  • What do I get at the end of an evaluation?

    You’ll receive a findings brief that ranks recommendations with evidence. Then there’s a working session where your team decides what to change first and who owns each change.

  • How do you keep our information secure?

    Everything you share is confidential by default. I'm happy to sign your NDA, or a BAA for health data, and I only access what a project needs.

  • Can you work with our in-house team or agency?

    Yes. I work through each finding with your designers, developers, or agency.

  • What if we don't have analytics or research yet?

    Early teams or products often start without research or analytics. In those cases a project starts from your product, website, and sales materials. Each finding says whether it came from expert review, best practices, or research with people. We can then establish a baseline and begin collecting data.

  • Do you work with companies outside Chicago?

    Yes. I work remotely with companies across the US and abroad.

Let's connect

Book an intro call
  • 30 minutes, free
  • You tell me where things stand
  • I take a first look at your product
  • Within 48 hours, you get a scoped proposal with pricesWithin 48 hours, you get a scope & approach with the price

After the call, you get a written scope & approach with timelines, options, & prices within 48 hours.

  1. Intro call30 minutes, free
  2. Scope & approachTimelines, options, & prices within 48 hours
  3. KickoffQuestions, first impressions, & quick wins